Newsletter
Join the Community
Subscribe to our newsletter for the latest news and updates

Multi-modal AI video workspace combining image, video, audio and text references into connected scenes up to 30 seconds with up to 50 inputs. Native 4K output
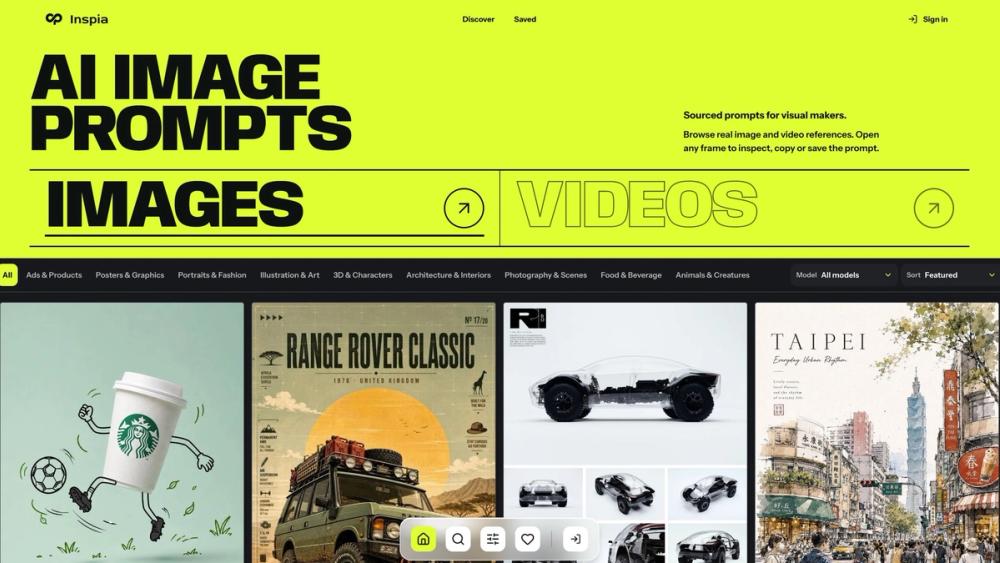
Inspia is a curated AI image and video prompt library where creators can discover real visual references, inspect the prompts behind them, and reuse ideas in their own work.
Transform your images into detailed AI prompts instantly, completely free and without any limits on generations.
Create stunning, cinematic videos with Veo 3, an advanced AI video generator powered by Google DeepMind, enabling users to generate high-quality videos from text and images.
Seedance 3.0 is a multi-modal AI video generation workspace that lets you turn a mix of image, video, audio, and text references into connected, production-ready scenes. Instead of describing a shot purely with text and hoping for the best, you feed the model the actual visual and audio materials you care about — a product photo, a reference clip of the motion you want, a music track for pacing — and it generates a video that respects all of them at once.
Each generation runs up to 30 seconds long and can be driven by up to 50 multi-media inputs (images, video clips, audio clips, and text references combined). Output is native 4K with no watermarks on paid plans, and optional 3D previz helps you block out shots before committing to a full render. Character and product consistency are handled natively: once you provide reference assets, the same person, product, or location stays recognizable across every scene in the sequence.
Seedance 3.0 is built around reference-driven generation rather than pure text-to-video. You combine:
The workspace fuses these references into one coherent generation, then lets you extend it seamlessly: generate a continuation of an existing clip, or create an entirely new scene that matches the same references.